Building Bespoke Fintech Agents Powered by Private AI

Most middle-market deal teams have now watched at least one demo of an AI agent summarizing a confidential information memorandum or populating a diligence tracker. Fewer have confronted what it actually takes to run that agent on confidential data without routing anything through a public model endpoint. The gap between pilot and production is where the architecture, governance, and build-versus-buy questions sit, and it is also where most middle-market initiatives stall.
The pressure to resolve those questions is building. Evident's Q4 2025 banking tracker found that generative and agentic AI use cases now account for 70% of banks' AI implementations, up from 54% a year earlier. Yet a July 2025 PYMNTS Intelligence survey found that only 15% of CFOs described themselves as ready to deploy agentic systems inside their organizations. The architecture gap, not the model capability gap, explains most of that spread.
Why Private Deployment Is the Default in Capital Markets
Private AI, in the sense used here, means a model and its retrieval stack running inside infrastructure the firm controls: on-premise, in a dedicated VPC, or in an air-gapped enclave. No prompts, embeddings, or retrieved documents transit a shared provider endpoint. For deal teams handling CIMs, management presentations, QoE drafts, and lender term sheets under NDA, that boundary is not a preference but a condition of being allowed near the data.
The cost side of the equation has shifted as well. The IBM Cost of a Data Breach Report 2025 put the global average breach at $4.44 million, with the U.S. average at a record $10.22 million. Financial services sat at $5.56 million per breach, the second-costliest sector after healthcare. A single exposure of a client's confidential deal file through a mis-scoped vendor integration can swamp the entire budget a boutique would have spent on AI tooling across several years.
Regulators have begun codifying what controls look like. In February 2026, the Cyber Risk Institute and 108 financial institutions published the FS AI RMF, the first sector-specific framework for generative AI in finance, with 230 controls spanning model risk, data governance, and operational resilience. Firms building agents today should expect counterparty due diligence questionnaires to begin referencing those controls directly.
The Reference Architecture for a Fintech Agent
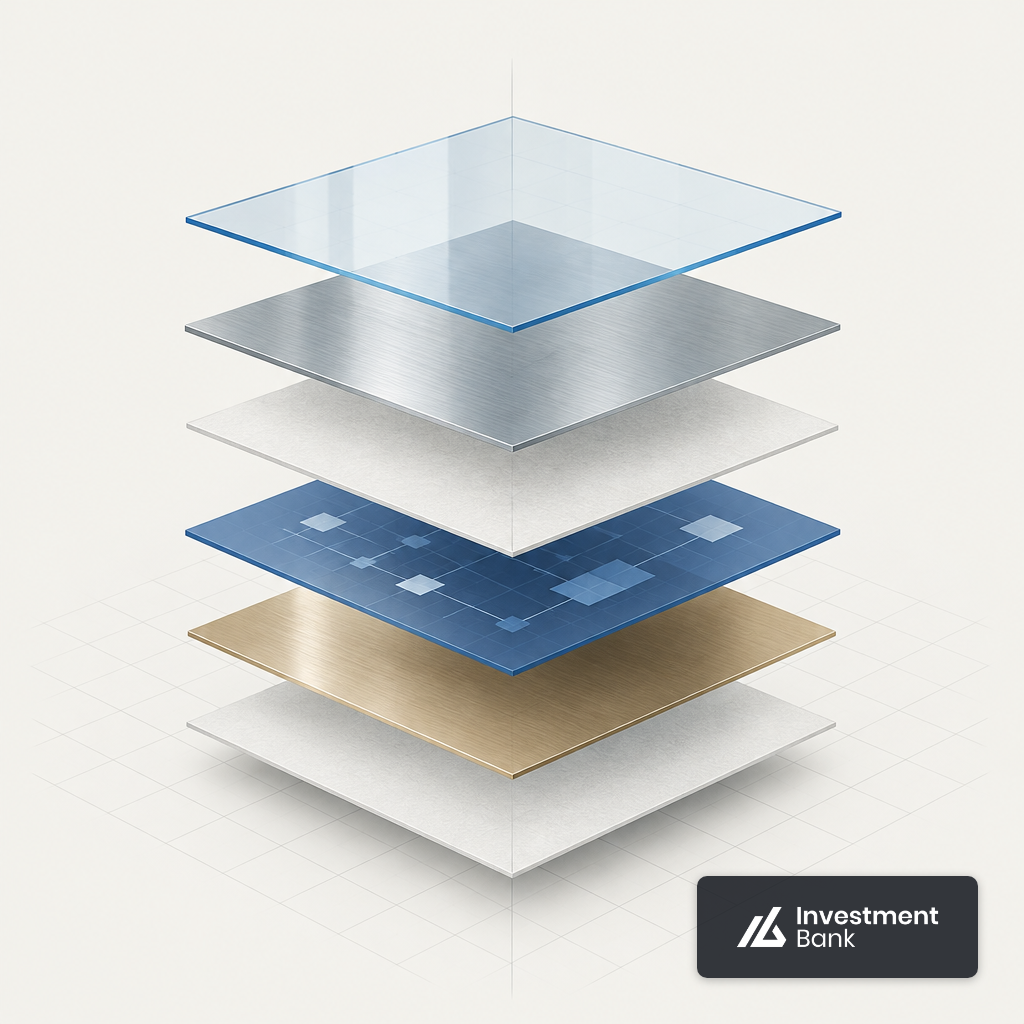
A bespoke AI agent for M&A work is less a model than a composition of six layers, each of which must be scoped and governed independently. The reference stack, drawn from current enterprise practice, has stabilized around the following components:
- Model layer. An open-weight LLM (Llama, Qwen, Mistral family) hosted in the firm's VPC or on-prem GPU cluster, often paired with a smaller routing model for triage.
- Retrieval layer. A vector store plus structured indices over the data room, prior CIMs, DDQ libraries, and precedent IC memos. Research on retrieval-augmented generation indicates RAG reduces hallucinations by 42-68%, with combined RAG, RLHF, and guardrail configurations driving a 96% reduction against baseline in a 2024 Stanford study.
- Tool layer. Narrow, typed APIs the agent can call: data room file fetch, financial model cell writes, calendar scheduling, DDQ status updates. Permissions should be least-privilege and schema-enforced.
- Orchestration layer. The planner that decomposes a task ("summarize this CIM against our IC memo template") into retrieval and tool calls.
- Guardrail layer. Prompt-injection filters, PII redaction, output validators, and escalation triggers for human review.
- Audit layer. Append-only logs capturing every prompt, retrieval, tool invocation, parameter, output, and reviewer action, with tamper-evident storage suitable for regulator or client review.
The audit layer is the one most frequently under-scoped and the one that determines whether an agent is defensible in a counterparty's diligence review. For a longer discussion of how these layers map to data room workflows specifically, see the earlier piece on AI in the virtual data room.
Build Versus Buy, Scoped Honestly
The build-versus-buy question for a middle-market firm rarely resolves to pure build. The practical choices are three: subscribe to a vertical SaaS platform that offers VPC or single-tenant deployment, license an on-prem model stack and compose workflows internally, or run a hybrid in which routine traffic is handled by a self-hosted open-weight model and only the hardest 5-15% of calls route to a frontier model under a zero-retention contract.
Cost figures from recent benchmarks make the trade-off concrete. A 2026 cost comparison from vdf.ai found that sustained high-volume workloads can run 50-85% below cloud API blended cost when hybrid routing is used, with break-even arriving at roughly 30-80 million tokens per month per GPU class. For a sell-side team running 20-30 live mandates, that threshold is reachable within a quarter once CIM drafting, DDQ triage, and buyer-list research are routed through the stack.
Capacity planning matters because budgets are moving fast. Deloitte's December 2025 AI Infrastructure Survey found 86% of enterprise respondents expect AI infrastructure budgets to more than triple over the next three years, and more than 70% plan to scale on-premise or edge deployments by 2028. Firms waiting for prices to fall are competing against counterparties who are compounding operational advantage now.
The staffing read is less flattering to the pure-build path. A credible internal deployment requires at minimum an ML engineer, a security engineer with model-risk background, a domain lead who can write and maintain evaluation sets drawn from real deals, and a compliance owner who signs off on each new tool permission. Below roughly $20 million in annual revenue, that headcount is difficult to justify against a vetted vendor on a VPC contract.
Governance That Survives a Regulator or a Buyer
Agents that touch deal data create three distinct governance surfaces. The first is model risk: the possibility that the agent produces a materially wrong output (a mis-stated covenant, a hallucinated add-back, a confused org chart) that enters a work product. The second is data governance: who can retrieve what, under which engagement, and with what retention. The third is operational: who approved each tool permission, who reviewed each flagged output, and what the escalation path looks like when the agent is uncertain.
Practical controls that hold up under counterparty review tend to share five features:
- Per-engagement data partitioning, with retrieval scoped to a single mandate's corpus and cross-mandate access blocked at the index level, not the prompt.
- Named human reviewers for any output that enters a client-facing deliverable, with the review captured in the audit log.
- Tool permissions granted per workflow and expired on engagement close, modeled on the same discipline a firm would apply to a UCC lien search or any other third-party data pull.
- Evaluation sets built from redacted historical deals, run before any model or prompt change ships to production.
- A documented incident response path covering prompt injection, data exfiltration via tool misuse, and model regression.
The payoff is measurable. The McKinsey research summarized by Neurons Lab notes that 50 of the world's largest banks announced more than 160 agentic AI use cases in 2025, and one U.S. bank's agent-generated credit risk memos delivered 20-60% productivity gains and a 30% improvement in credit turnaround. Those gains are reachable in middle-market deal workflows, but only when the governance stack is treated as a precondition rather than a post-launch cleanup.
Where Agents Earn Their Keep in a Live Mandate
The highest-leverage early workflows are the recurring, template-driven ones where the quality bar is "accurate first draft that a senior reviews," not "final deliverable." CIM review automation, in which the agent extracts financials, customer concentration, and management bios from a target's materials into a standardized working template, is the most common entry point. DDQ response drafting against a firm's prior-answer library is a close second. Buyer or target list enrichment, parsing of QoE reports for exception items, and preparation of initial IC memo sections round out the top five.
Sell-side process economics make the business case straightforward. A fuller breakdown appears in the piece on sell-side engagement costs, but at a high level, an associate hour redirected from CIM drafting to buyer outreach or diligence coordination compounds across a mandate. The earlier piece on where AI is replacing banker tasks covers the task-level view; this one is the architectural counterpart.
What agents do not yet earn their keep on is anything requiring judgment under adversarial conditions: negotiation strategy, materiality calls on diligence findings, or client communication at inflection points. Firms that have deployed well tend to describe their agents as a well-supervised associate class, not a replacement for the deal team.
A Pragmatic Starting Point
For a middle-market firm considering its first production agent, the sequence that has worked in practice is narrow before broad. Pick one workflow with a clear quality bar, a reusable template, and a bounded data scope. Stand up a VPC-isolated model with retrieval over the relevant corpus, enforce least-privilege tool access, and instrument the audit layer before the first user prompt. Measure accuracy against a labeled evaluation set, not against user sentiment. Expand to a second workflow only once the first has run for a full engagement cycle with incident-free reviews.
The firms that will be competitive on fees and turnaround in 2027 are not the ones with the largest model subscriptions. They are the ones that treated the private AI stack as deal infrastructure, governed it as such, and let the compounding show up in staffing ratios and cycle times. The architecture is now well enough understood that waiting is itself a strategic choice.
Considering a transaction?
Speak with our advisory team about your sell-side, buy-side, or capital needs — in confidence.